


Gateworks GW16168 M.2 AI accelerator features NXP Ara240 DNPU with up to 40 eTOPS
Mar 10, 2026 — by Giorgio Mendoza 606 views Gateworks has introduced the GW16168, an M.2 AI acceleration card designed to add dedicated neural network processing to embedded and industrial systems. The module integrates NXP’s Ara240 discrete neural processing unit (DNPU) and is designed, tested, and assembled in the United States for industrial edge AI deployments.
The GW16168 uses NXP’s Ara240 DNPU to deliver up to 40 equivalent eTOPS of AI inference performance. The card is intended to offload AI workloads from host processors, allowing embedded systems to run machine vision, large language model inference, and other AI workloads without saturating the host CPU.
— ADVERTISEMENT —
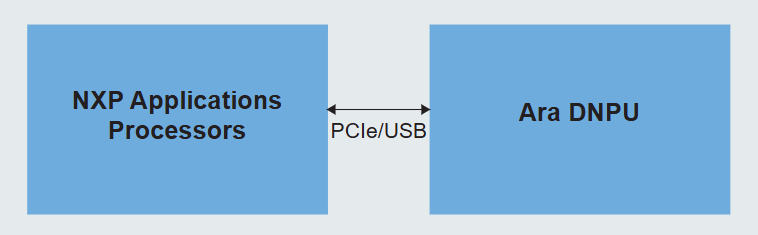
Ara240 DNPU connection to host processors
The accelerator includes 16GB of onboard LPDDR4 memory, allowing neural network workloads to run independently of host system memory. According to Gateworks, the module can support models with up to 30 billion parameters using INT4 quantization, enabling more complex AI workloads on embedded edge platforms.

Ara DNPU runtime integration w/ host processors and drivers
The card uses a standard M.2 M-Key 2280 form factor and connects through a PCIe Gen4 x4 interface, while remaining compatible with PCIe Gen3 hosts. This design allows the accelerator to be integrated into embedded platforms such as Gateworks’ VeniceFLEX and Catalina single-board computers, as well as other compatible M.2-enabled systems.
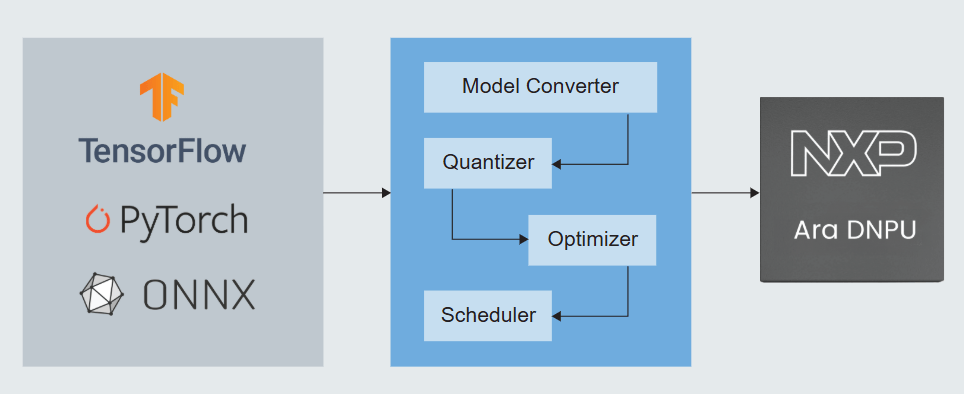
Ara240 machine learning deployment workflow
Thermal design is centered around the passively cooled Ara240 DNPU. Gateworks reports a typical power consumption of about 6.6W, enabling operation in fanless industrial systems while maintaining performance for sustained inference workloads.
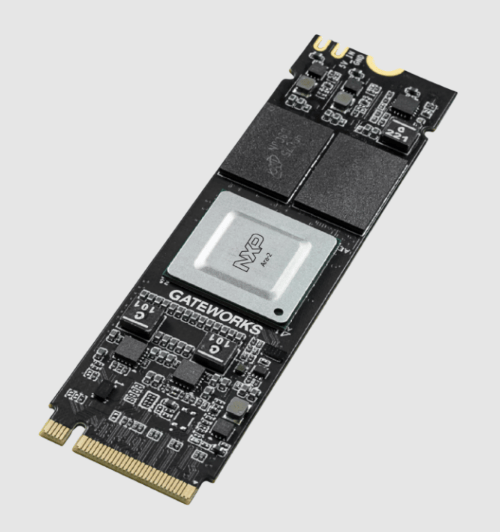
Gateworks GW16168 M.2 AI accelerator w/ NXP Ara240 DNPU
The accelerator is supported by the NXP Ara SDK, which provides tools for model conversion, optimization, and deployment.
The software stack supports common AI frameworks including TensorFlow, PyTorch, and ONNX, allowing existing models to be converted and deployed on the hardware.
Specifications listed for the GW16168 include:
- NPU:
- NXP Ara240 discrete neural processing unit
- AI performance:
- up to 40 eTOPS
- Memory:
- 16GB LPDDR4
- Interface:
- PCIe Gen4 x4 (compatible with Gen3 hosts)
- Form factor:
- M.2 M-Key 2280
- Model support:
- up to 30B parameters (INT4)
- Security:
- secure boot and root of trust
- Operating temperature:
- –40°C to +85°C
- Typical power consumption:
- ~6.6W
Further Information
The GW16168 AI accelerator card and associated development kit are expected to ship in late May, with distribution planned through DigiKey, Braemac, RoundSolutions, and Avnet. Pricing has not yet been announced.
any llama benchmark?
I’m waiting for maverick 2 for AI